sprag-doc2md
Reads the Markdown that sprag doc2md converted instead of the binary document, with no denied Read in between
newguardstatuspromptprocess

Reads the Markdown that sprag doc2md converted instead of the binary document, with no denied Read in between
<img alt="Sprag" src="https://raw.githubusercontent.com/rootstudioyaml/sprag/main/site/assets/logo/sprag-lockup-light.svg" width="220">
Cut the tokens Claude Code and Codex spend, from the first session.

<a href="https://sprag.io/assets/video/sprag-compare-en.mp4"><img src="https://raw.githubusercontent.com/rootstudioyaml/sprag/main/docs/sprag-compare-en.gif" width="760" alt="Two terminals receive the same twelve requests. With Sprag, lookups and test runs go to cheaper models and documents go in as Markdown; the day ends at $1.83 against $6.68 without Sprag."></a>
Same 12 requests, two terminals: $6.68 → $1.83 (−72.6%) with Sprag.<br> <sub>Example requests priced at public list rates. <a href="https://sprag.io/assets/video/sprag-compare-en.mp4">Full video (41s)</a></sub>
Sprag saves tokens without changing how you work. Lookups, checks and test runs go to a cheaper model, documents reach the context as compact Markdown (a 540k-token deck becomes 23k tokens), and the statusline shows what each session spent and saved while it runs. npm i -g sprag-cli sets it all up; nothing to configure per project.
Sprag is named after the sprag clutch: forward motion passes, backspin locks. Your agent keeps working, it just stops regressing.
It reads the sessions you already ran, and what it finds there holds for every session after. Repeated failures become rules loaded at session start. Work that a cheaper tier has never got wrong goes to a sub-agent on that tier, and every delegated run writes its own price difference to a ledger. Cache and rate-limit trouble reaches your statusline while you can still act on it.
Session analysis runs locally on the logs Claude Code and Codex already write. No extra model calls or API key are needed for analysis. Optional Codex gateway budget and price lookups contact your configured LiteLLM endpoint using its existing credentials. The CLI requires Node.js 18+ and one TOML parser dependency.
npm i -g sprag-cli # Claude Code, plus Codex when it is installednpm i -g sprag-cli. Hooks, the statusline and the starter rules are set up for every project; there is nothing to configure per project. If you already have a statusline, the install asks whether to show both, replace yours, or keep yours.🔀 Routing saved $188 | opus→sonnet ×67 $93.4 · fable→sonnet ×26 $83.7 · opus→haiku ×25 $7.41 · fable→haiku ×6 $3.73
🧠 Cache hit 98.8% · ⏳ Cache expires 59:46 · 🅷 5/5 · 📦 Ctx 47% of 1MSprag never swaps the model you picked. Analysis reads your local session logs only, with no extra model calls and no API key. sprag uninstall removes everything it added and restores a statusline it merged with.
Using Codex? See Codex below.
<img src="https://raw.githubusercontent.com/rootstudioyaml/sprag/main/docs/how-it-works.png" alt="What goes in: your past sessions, the task you just asked for, a document you would attach, Korean prose being written, and the tokens this turn is spending. What sprag does with it: writes a ratchet rule loaded every session, converts the document, checks the Korean as you write, prints the cost in your prompt, and routes a matched task to a haiku or sonnet sub-agent whose output the main agent reviews.">
Everything on the left is something your session already produces. Nothing is sent anywhere to read it. The tier decision at the bottom is the whole routing argument in three tests: where the answer lives, whether a mistake surfaces, and what error rate the rule was measured at.
Sprag does not swap the model you asked for. It reads what you have already run, finds the kinds of task that never went wrong on a cheaper tier, and spawns a sub-agent for exactly those. The main agent reviews what comes back before anything counts as done, and the work returns to it the moment a rule stops holding.
| Metric | Result | Evidence | |
|---|---|---|---|
| Public benchmark accuracy | 59.1% vs 57.9% best single model | ▰▰▰▰▰▰▰▰▰▰▰▰ | benchmark |
| Cost for the same queries | $268 vs gpt-5 $388, gemini-2.5-pro $734 | ▰▰▰▰▰▱▱▱▱▱▱▱ | benchmark |
| Tokens for the same documents | −95.9%, 2,011,178 → 82,209 over 12 files | ▰▱▱▱▱▱▱▱▱▱▱▱ | doc2md |
| Delegation savings, from the ledger | $188.27 over 124 delegated runs | ▰▰▰▰▰▰▰▰▰▰▰▱ | sprag route-scan savings |
| Cheap tier on the same prompts | 24% of the cost, one answer worse out of eight | ▰▰▰▱▱▱▱▱▱▱▱▱ | A/B run |
The first two rows answer the objection that comes up first: that moving work to a cheaper model has to cost you accuracy. It did not. The same criteria, wired up as a router, scored 1.2 points above the best single model at a third of the cost. Nothing is best at everything, which is why choosing per task beats choosing once.
Measured offline on LLMRouterBench (Findings of ACL 2026): 11,696 instances, 13 models whose answers, scores and costs ship with the dataset. No model was called and nothing was spent. The router chose; the numbers were looked up. Run it again and you get the same figures. It validates the criteria, not sprag's own routing: the dataset has no Claude models, so deepseek-v3, qwen3-235b and gpt-5 stood in for cheap, mid and flagship.
The last three rows are ledgers on this machine. They grow as it runs. The routing figures were read on 2026-10-09, the document figures on 2026-09-18. Model names are the ones each run actually used.
🔀 Routing saved $188.27 total        (last 7d $13.31 · last 30d $150.64)

   fable-5 → sonnet-5      24 runs    $81.19   ▰▰▰▰▰▰▰▰▰▰▰▰
   opus-5  → sonnet-5      54 runs    $68.85   ▰▰▰▰▰▰▰▰▰▰▱▱
   opus-5  → sonnet-5.5    13 runs    $24.58   ▰▰▰▰▱▱▱▱▱▱▱▱
   opus-5  → haiku-4.5     25 runs     $7.41   ▰▱▱▱▱▱▱▱▱▱▱▱
   fable-5 → haiku-4.5      5 runs     $3.22   ▰▱▱▱▱▱▱▱▱▱▱▱
   fable-5 → sonnet-5.5     2 runs     $2.51   ▰▱▱▱▱▱▱▱▱▱▱▱
fable-5 → haiku-5.5 1 run $0.51 ▰▱▱▱▱▱▱▱▱▱▱▱| Also measured | Over 30 days | |
|---|---|---|
| Documents converted | 12 files, 2,011,178 → 82,209 tokens | ▰▱▱▱▱▱▱▱▱▱▱▱ |
| Cache hit rate | 92.2% | ▰▰▰▰▰▰▰▰▰▰▰▱ |
| Volume behind both | 175 sessions · 14,682 API calls · 3.81B input tokens |
Real output, from sprag route-scan savings, sprag --days 30, and the doc2md ledger. Nothing here is a projection.
Every delegated run records its own price difference, so sprag route-scan savings traces any amount back to the rule that caused it. What the ledger deliberately leaves out is written down in the command reference.
The tier criteria are not a hunch. Each one traces back to published routing research, and the percentages quoted in the rules (28% vs 54% recall, a +63pp gap on chained tool work) are sprag's own offline measurement on the datasets below.
| Criterion | What the paper found | Paper |
|---|---|---|
| Delegate down, conservatively | As budgets grow, learned routers default to the most expensive model even when a cheaper one already suffices. | Lai & Ye, When Routing Collapses: On the Degenerate Convergence of LLM Routers (2026) |
| Judge difficulty by outcome | Every router on the board falls short of the oracle, mainly because it cannot tell when a smaller model is enough. Query difficulty is defined by how many of 42 models actually answered it. | Lu et al., RouterArena: An Open Platform for Comprehensive Comparison of LLM Routers (2025) |
| Thresholds from your own logs | Routing compares a predicted win rate against a cost threshold, and results are read by the share of calls sent to the strong model. sprag sets that threshold from your last 14 days at every scan. | Ong et al., RouteLLM: Learning to Route LLMs with Preference Data (2024) |
| Escalate on failure | A cascade tries the cheap model first and lets a check on the answer decide whether to go up. It matched GPT-4 with up to 98% lower cost. | Chen, Zaharia & Zou, FrugalGPT (2023) |
| Where the answer lives | Short-form factual recall measured on its own. The 28% vs 54% recall gap comes from this class of set. | Wei et al., Measuring short-form factuality in large language models (SimpleQA) (2024) |
| Tool orchestration stays up | Agents must coordinate tool calls with a user in a shared environment. The +63pp gap was measured here. | Barres et al., τ²-Bench (2025) |
| The public benchmark run | 400K instances, 21 datasets, 33 models. Several routers, commercial ones included, fail to beat a simple baseline. | Li et al., LLMRouterBench (Findings of ACL 2026) |
| Routing vs cascading | A taxonomy of when a routing decision is made, what it reads, and how it is computed. | Moslem & Kelleher, Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey (2026) |
Two criteria have no paper behind them. Batching tasks that read the same files and splitting design from code writing come from sprag's own cost accounting: on a sub-agent, loading context costs more than generating. The full reasoning, in Korean, is in Tier criteria.
| What it does | More | |
|---|---|---|
| ⚙️ Ratchet rules | Repeated failures become one-line rules loaded every session. Candidates are detected from your logs, and you choose project or global scope. | harness |
| 🔀 Model fitting | Log-driven delegation rules carrying the error rate they were measured at and the savings they reported, written to ratchet-model.md. | route-scan |
| 🅷 Harness score | Five operating principles checked live. Skip the verify step and 🅷 4/5 says so before you report done. | harness |
| 📊 Token telemetry | Cache hit rate, TTL, context size, output spikes and both rate-limit windows, in the prompt every turn. | statusline |
| 📄 doc2md | pptx, xlsx, pdf, docx and fig converted on demand, so a document costs one read instead of your whole context. | doc2md |
| 🇰🇷 Style gates | Write-time prose lint enforced by hook. Shipping today for Korean technical writing: double passives, translationese, cohesion. | style |
The two savings figures are never added together. They measure different things: the routing ledger records the price difference on delegated runs, and the conversion ledger records tokens a document did not cost.
Neither one counts what the harness and the ratchet rules save. That saving arrives as fewer round-trips rather than as cheaper ones.
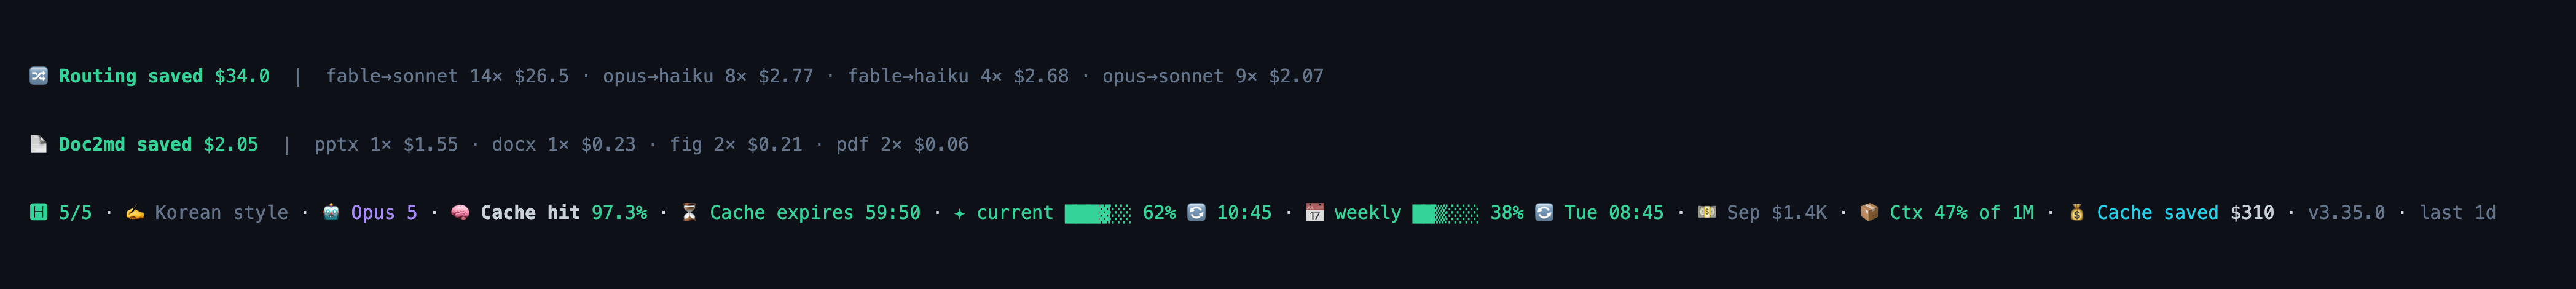
🔀 Routing saved $188  |  opus→sonnet ×67 $93.4 · fable→sonnet ×26 $83.7 · opus→haiku ×25 $7.41 · fable→haiku ×6 $3.73
🚨 5H ▰▰▰▰▰▰▰▰▰▰▰▱ 94% 🔄 12:36 · 🅷 5/5 · 🤖 Opus 5.5 · 🧠 Cache hit 98.8% · ⏳ Cache expires 59:46 · 📅 weekly ▰▰▰▰▰▱▱▱▱▱▱▱ 38% · 💵 Sep $42 · 📦 Ctx 47% of 1M
When something is wrong the warning chip leads the line: 🚨 5H/7D NN%, ⚠ Ctx 500k+, ⚠ Cache miss, ⚠ Input spike, ⚠ Output heavy, ⚠ Call surge, ⚠ Rebuild churn, ⚠ 5m TTL. Paste the chip text into Claude and the Skill names the root-cause code and the fix. Every segment is explained in the statusline reference.
Inside a JetBrains IDE terminal the chips render as single-cell glyphs instead of emoji (◉ Cache hit 98.8% · ◧ Ctx 47% of 1M). The IDE's default font has no emoji glyphs, so emoji leave characters from the previous frame on screen, like Cache expires 4:545. Label modes covers the detail, plus sprag mode narrow and mode icon-force.
The benchmark uses public data. This asks the same question of my own work: eight prompts from real sessions in this repository, sent to both tiers, graded against an answer written before the run (2026-09-17, raw data in video/out/measure2.json).
| flagship (opus-5) | cheap tier (haiku-4.5) | |
|---|---|---|
| Cost for all eight | $2.5652 | $0.6132 (23.9%) |
| Graded correct | 7 / 8 | 6 / 8 |
| Gave the same answer | 6 / 8 |
The prompt both tiers missed is the useful one. It asked which files reference process.env without saying whether subdirectories counted, and the two read it differently. Adding that one condition made their answers identical. The question was ambiguous, not hard.
The remaining miss is the cheap tier leaving entries out of a file listing. A wrong listing is one you can see is wrong, which is the second criterion doing its job.
So the cheap tier is not free. On this sample one lookup in eight comes back worse, for a quarter of the price. That is why rules only send work whose failure surfaces, and never send design or diagnosis.
| Measured | Value | Sample | Window |
|---|---|---|---|
| Documents converted | 2,011,178 → 82,209 tokens | 12 files (xlsx, pptx, pdf) | to 2026-09-18 |
| Delegated runs | $188.27 saved, $1.52 per run | 124 runs | to 2026-10-09 |
| Ratchet rules accumulated | 37 (30 global, 7 per-project) | 4 repositories | 2026-05-08 to 09-16 |
The two counts grow differently. Ratchet rules come from mistakes a person made, so they keep coming. Delegation rules stop: the criteria recognize a fixed set of work types, and once each has a rule there is nothing left to promote.
Native hooks, an AGENTS.md harness, scoped ratchet rules, Korean lint, document conversion, token reports, and a session-bound companion panel. npm i -g sprag-cli sets Codex up too when it is installed, with the rule presets registered globally and nothing asked (sprag install --manual asks at each step). For a Codex-only install that leaves Claude Code alone:
npm i -g sprag-cli --ignore-scripts
sprag install --agent codex
sprag --agent codex --days 7
sprag panel --agent codex  # live companion in a separate terminal
sprag --statusline --agent codex --text
sprag doctor --agent codex  # troubleshooting only
sprag route-scan --agent codex
sprag seed --agent codex
Review and trust the new hooks in Codex's /hooks menu; Codex requires that step. Commands still default to Claude Code; add --agent codex to pick Codex. Codex also supports session briefings, warning history, handoffs, and opt-in model routing and subagent guidance (sprag delegate on --agent codex). The native Codex footer does not accept shell commands; Sprag provides a terminal statusline and panel. Recurring simple turns become route candidates; repeated tool failures become ratchet candidates. Both require your approval before a rule is registered. seed offers compatible starter rules with separate Codex decisions. sprag route-scan savings --agent codex records only Sprag-routed child runs and estimates their price difference when matching LiteLLM prices are available. It is not a billing measurement. Unknown prices remain n/a, and Codex document counts stay separate from Claude estimates. The historical dollar figures below are from Claude Code, not a Codex benchmark. See Codex support and limits, or run sprag capabilities --agent codex for the support matrix.
| Workflow | Claude Code | Codex |
|---|---|---|
| Session instructions | CLAUDE.md and hooks | AGENTS.md and native hooks |
| Live telemetry | Native statusline command | Companion panel or tmux layout |
| Rule candidates | Claude transcripts and tier presets | Codex rollouts and compatible ratchet presets |
| Model routing | Haiku/Sonnet tier rules | Explicit provider model IDs and scoped rules |
| Routing ledger | Claude run estimates | Attributed child estimates with LiteLLM prices |
Both integrations coexist. Commands without --agent codex retain Claude behavior.
| Command | What it does |
|---|---|
sprag | Last-30-day diagnostic report |
sprag handoff | Back work up to markdown before a cap blocks you |
sprag route-scan | Find delegation candidates in your own history (0 LLM calls) |
sprag route-scan savings | The routing-savings ledger |
sprag harness check | Current 🅷 harness score |
sprag doc2md <file> | Convert one document to Markdown |
Every subcommand, flag and the output-language setting: command reference.
| Doc | Covers |
|---|---|
| Codex | Installation, panel, native hooks, automatic candidates, presets, and accounting limits |
| Install | What the install turns on, what stays manual, how to turn each part off |
| Statusline | Segments, warning chips, spike issue codes, update notifications |
| Commands | Full CLI surface |
| Harness | The five principles, rule promotion, compact-window pinning, seed presets |
| route-scan | Tier verdicts, rule-file mechanics, scan triggers, subagent setup |
| Tier criteria | Why T0/T1/T2 split where they do, with sources (Korean) |
| Benchmark | The 11,696-instance LLMRouterBench run |
| doc2md | Supported formats, savings evidence, editing documents, DRM cases |
| Korean style | What gets injected, the write-time check, before/after |
| Not a router | Why realtime routing breaks the cache and costs more |
| Gateways & environment | Bedrock, Vertex, LiteLLM budgets, pricing table, FAQ, how it works |
| Reduce Claude Code tokens | Compact/clear timing, subagent exploration, document conversion, cache TTL |
| Claude Code usage limits | The 5-hour and 7-day windows, watching both, cutting per-turn cost |
| Codex token usage | Session scoping, native subagent delegation, document conversion for Codex |
| Compare | Sprag vs ccusage, claude-usage, and statusline tools like CCometixLine |
Behind a LiteLLM gateway, sprag profile-map --refresh now reads model aliases straight from the gateway's own GET /model/info, so route-scan no longer needs to wait on learned votes or a hand-edited profile-map.json. The refresh uses the same 5-minute check and 24-hour cache as the LiteLLM budget gauge. It never stores your auth token: each refresh reads it from apiKeyHelper at call time and lets it expire on the helper's own schedule. Details: route-scan.
The full history moved to CHANGELOG.md (Korean; version headings and command names are language-neutral). Recent changes:
AGENTS.md harness rules, a session-bound companion panel, document conversion, diagnostics, and opt-in delegation. Codex usage accounting stays separate from Claude Code. See the Codex guide.feedback subcommand for filing bug reports and feature requests straight from the terminal or a Claude session, via the gh CLI, an anonymous no-login form (auto-filed as a GitHub issue by an Apps Script relay), or a local fallback. install now asks before replacing an existing statusline instead of silently skipping.cohesion on turns the language-neutral cohesion rules from the Korean supplement into a standalone English injection (given-before-new, one referent per pronoun, subject consistency, bridging, merging choppy sentences). Opt-in, ~0.5k tokens per session, suppressed while korean on already carries them.💵 Sep $42 segment now shows estimated spend since 00:00 on the 1st of the current month, always on, including gateway setups with no 5h/7d caps. LiteLLM gateway users get a 🔑 budget ▰▱ 34% $34/$100 gauge built from the key's budget (GET /key/info + GET /user/info, team-membership budget first, then key, then internal user, verified against a Dockerized LiteLLM).Bugs and feature requests go in the issue tracker: https://github.com/rootstudioyaml/sprag/issues
With no browser or GitHub login at hand (corporate network, mid-session), submit straight from the terminal instead, or ask Claude to do it for you:
sprag feedback "the 5m TTL chip never clears on Bedrock"It files a GitHub issue through the gh CLI when one is authenticated. Otherwise
hooks/register.ts 125 lines1import type { EngineInterface, Register } from 'claude-code'
2
3/**
4 * sprag-doc2md: the mod form of sprag's PreToolUse(Read) hook.
5 *
6 * The settings hook can only refuse the Read and tell Claude where the
7 * converted Markdown is, which costs one more tool call per document. A mod
8 * sits in front of the call, so it hands the same call on with the path
9 * swapped: Claude asked for deck.pptx and reads deck.md, and the permission
10 * check still runs on the path that is actually read.
11 *
12 * Whenever this mod does not redirect (not a document, conversion refused or
13 * failed, sprag not on PATH) the call goes on untouched, and sprag's settings
14 * hook beneath it explains the refusal exactly as it does today. After a
15 * redirect that hook sees a .md path and stays silent, so the two never
16 * answer the same Read twice.
17 *
18 * The exception is an encrypted document (password or DRM). Claude Code
19 * refuses a pptx, xlsx or docx as a binary file before any settings hook runs,
20 * so the settings hook can never tell the model why such a file cannot be
21 * read; this mod is the only place that can, so it refuses the Read itself
22 * with the CLI's notice.
23 */
24
25// Mirrors TARGET_EXTENSIONS in src/doc2md.cjs. A hooks module has no Node, so
26// it cannot load that file; test/mod-install.test.js holds the two in step.
27const TARGET = /\.(pptx|xlsx|xls|pdf|docx|fig)$/i
28
29// The CLI's name, as CLI_NAME in src/cli-name.js spells it. The mod cannot
30// import that file either; test/mod-install.test.js holds the two in step.
31const CLI = 'sprag'
32
33// The converter gives up at 120 s on its own; the margin covers CLI start-up.
34// Time spent in $.process.run does not count against the hook's 10 s budget,
35// so the Read waits as long as the conversion does, as it does under the
36// settings hook today. The status line says so while it lasts.
37const CONVERT_TIMEOUT_MS = 150_000
38
39// What `sprag doc2md <path>` prints on success. Parsing human output is a
40// prototype shortcut: a `--json` flag on that command should replace it.
41const CONVERTED = /^✓ (cached|converted): (.+)$/m
42
43// What `sprag doc2md <path>` prints on stderr for an encrypted document: the
44// reason line, then one indented line holding the notice for the model. A CLI
45// that predates the notice line prints the reason line alone.
46const LOCKED = /^✗ (encrypted|drm-protected)\b.*$/m
47
48type Converted = { cacheFile: string; isCached: boolean }
49type Locked = { locked: string }
50
51const baseName = (path: string) => path.split(/[\\/]/).pop() ?? path
52
53/**
54 * Runs the conversion the settings hook would run, ledger entry included.
55 * Answers null on any failure so the caller passes the event on unchanged,
56 * and `{ locked }` with the CLI's notice when the document is encrypted.
57 *
58 * A first conversion can take a minute, and nothing else on screen says the
59 * Read is waiting on it, so the status line under the prompt names the file
60 * until the CLI returns. A status line rather than a transcript line: whether
61 * the file is cached is unknown until the CLI answers, and a log line on every
62 * Read would double the lines for the cached ones too.
63 */
64async function convert($: EngineInterface, path: string): Promise<Converted | Locked | null> {
65 $.ui.status(`doc2md: ${baseName(path)} 변환 중…`)
66 try {
67 const run = await $.process.run([CLI, 'doc2md', path], { timeoutMs: CONVERT_TIMEOUT_MS })
68 if (run.exitCode !== 0) {
69 const reason = LOCKED.exec(run.stderr)
70 if (!reason) return null
71 const rest = run.stderr.slice(reason.index + reason[0].length)
72 const notice = rest.split('\n').map(line => line.trim()).find(line => line !== '')
73 return notice ? { locked: notice } : null
74 }
75 const match = CONVERTED.exec(run.stdout)
76 if (!match) return null
77 return { cacheFile: match[2].trim(), isCached: match[1] === 'cached' }
78 } catch {
79 return null
80 } finally {
81 $.ui.status(undefined)
82 }
83}
84
85const isLocked = (doc: Converted | Locked): doc is Locked => 'locked' in doc
86
87function logRedirect($: EngineInterface, from: string, doc: Converted) {
88 $.ui.log(`doc2md: ${baseName(from)} 대신 변환본을 읽습니다${doc.isCached ? ' (캐시)' : ''}`)
89}
90
91export const register: Register = on => {
92 // Both hooks fail open, which is the point of the .catch on each: a hook that
93 // breaks hands the event on as it came and sprag's settings hook beneath
94 // answers as before. Only the encrypted-document refusal in the Read hook guards
95 // anything, and failing open there costs the notice, not safety.
96 // Where the hook had already called next, next(e) replays that call.
97 on('tool.call', { tool: 'Read' }, async ($, e, next) => {
98 if (!TARGET.test(e.file_path)) return next(e)
99 const doc = await convert($, e.file_path)
100 if (!doc) return next(e)
101 // Refuse rather than pass the original on: it cannot be opened, and the
102 // binary-file refusal it would meet says nothing of why.
103 if (isLocked(doc)) return { deny: `[doc2md] ${doc.locked}` }
104 logRedirect($, e.file_path, doc)
105 // Line and page ranges addressed the binary and mean nothing in the
106 // Markdown (`pages` applies to PDFs only), so the whole file is read.
107 const { offset: _offset, limit: _limit, pages: _pages, ...call } = e
108 return next({ ...call, file_path: doc.cacheFile })
109 }).catch(($, e, next) => next(e))
110
111 // An @-mentioned document is attached whole, before any tool call, so the
112 // Read hook above never sees it. Redirect the attachment the same way.
113 on('prompt.mention', { path: TARGET }, async ($, e, next) => {
114 const doc = await convert($, e.path)
115 // A deny here would only reach the debug log, not the model, so an
116 // encrypted mention goes on as it came; the prompt hook names it instead.
117 if (!doc || isLocked(doc)) return next(e)
118 logRedirect($, e.path, doc)
119 // A mention carries no `pages` (PromptMentionInput has mention, path,
120 // offset, limit and agentId), so only the line range is dropped here.
121 const { offset: _offset, limit: _limit, ...mention } = e
122 return next({ ...mention, path: doc.cacheFile })
123 }).catch(($, e, next) => next(e))
124}
125