jev-blindspot-band
A one-glance summary of jev-blindspot in the band above the prompt: the blind spot count, the deeper question, and the top findings for the prompt you just…
newbandpromptnetworktimer

A one-glance summary of jev-blindspot in the band above the prompt: the blind spot count, the deeper question, and the top findings for the prompt you just…


Good results start with good requests.
jev-blindspot is a prompt reviewer for Claude Code and Codex CLI that runs alongside your session and shows its reviews in a local web UI.
Each time you submit a prompt, Jev decides whether a review is needed. If so, a lightweight model provides quick feedback on what your request may have overlooked, including missing context, unstated assumptions, or the underlying problem. The review helps you decide what may need clarification.
It does not block your prompt, edit it, or add anything to the agent's context. Your prompt goes through as written, and you decide whether to act on the review.
<img src="https://raw.githubusercontent.com/jsk4581/jev-blindspot/main/docs/panel.png" alt="The jev-blindspot web UI in a browser tab">
Now supports Claude Code Mods, so you can view it directly in the CLI. <img src="https://raw.githubusercontent.com/jsk4581/jev-blindspot/main/docs/band.png" alt="The jev-blindspot band above the Claude Code prompt">
Node 20 or newer, a TypeSafe API key, and Claude Code or Codex CLI already logged in.
npm install -g jev-blindspot
mkdir -p ~/.config/jev-blindspot
echo 'TYPESAFE_API_KEY=your-key' > ~/.config/jev-blindspot/env && chmod 600 ~/.config/jev-blindspot/env
jev-blindspot install-hook      # hooks into every agent it finds
For Codex, also trust the new hook once: jev-blindspot install-hook codex --trust, or /hooks inside Codex. Details in Install.
Then type /blindspot in Claude Code, or /prompts:blindspot in Codex. The web UI's URL comes back in the session at once, with no model turn spent. Open it in a browser tab next to the session and keep working as usual.
From then on, every prompt you submit becomes a card in the web UI: quiet when there is nothing to consider, otherwise the blind spots of that request, each with a sentence you can paste into the next prompt. The card also shows what the check cost: the model, the time, the tokens in and out, and for Claude the dollar amount and the number of turns. Nothing changes in the session itself.
To get good work out of an AI you have to ask for it well, and asking well means knowing the work. The skill that matters most here is knowing what you do not know. A request written without that knowledge is not wrong; it is silent about the questions it never knew were there, and the answer will be silent about them too. Those gaps are invisible from the inside. You cannot list what you did not think of.
Prompt linting tries to fix this at the input, and pays for it in exactly the places that matter: it intercepts what you typed, makes you wait, and spends tokens on every prompt whether or not there was anything to find.
jev-blindspot moves the check out of the way. A single classifier call first decides whether the prompt is worth a second look at all. Only then does a light model go looking, in the project directory, for what the request did not consider. That happens in the background while the agent is already working, and the result appears in a separate tab, where you can fold it into the next request. Nothing is inserted into the session.
jev-blindspot reviews the request only. It does not inspect or predict what the assistant does with it. It is a thinking aid: it keeps showing you the questions you did not know to ask, in work you know well and in work you do not.
Two stages run for every prompt. The first is a single classifier call on every prompt; the second is a model run that happens only when the first stage returns a positive decision.
Gate: TypeSafe jev, one request. jev answers a fixed set of typed questions about a state object and returns probabilities instead of text. The gate sends seven questions in one call. Two of them decide:
worth_checking: does this request have a blind spot? Is there somethinganyone who knows this kind of work would have considered, that the request shows no sign of, and that would change the result? Things the author clearly left out on purpose do not count.
risk: a five-level rubric from read-only to irreversible (delete, forcepush, real sends, production data). High risk lowers the worth_checking bar.
Four more are the knowledge-gap taxonomy from Towards Detecting Prompt Knowledge Gaps for Improved LLM-guided Issue Resolution (arXiv:2501.11709): missing context, missing specification, unclear instruction, several requests bundled. The last, deeper_problem, asks whether the request reads as a means rather than the end: a step toward a larger goal, a workaround for a symptom, or a question that depends on a more fundamental one. These five never decide anything. They appear as chips on the card as soon as the gate returns and go to the second stage as hints.
Only questions with a closed answer set go to jev. Which kinds of knowledge the request calls for, and what exactly it did not consider, are open questions and go to the second stage.
Brain: the agent's own headless mode. When the gate passes, the daemon runs a model on the login you already have, in the project directory, with read-only file access. The run matches the agent the prompt was typed into:
| prompt typed into | brain run | project instructions |
|---|---|---|
| Claude Code | claude -p --model sonnet --effort low with Read, Grep and Glob | CLAUDE.md loads as in a normal session |
| Codex CLI | codex exec -m gpt-5.6-luna with low reasoning effort, a read-only sandbox and hooks disabled | AGENTS.md loads as usual |
The model reads what the request touches, and the effort level is the only brake. It decides for itself which kinds of knowledge the request calls for, then returns up to five items: the consideration that is absent, why it matters for this request, and a sentence you can paste into the next prompt. When the request stands on a more fundamental request, problem or question the author has not asked, the brain also names that one, at most one per turn, and the card shows it above the blind spots as the deeper question. Most turns have none. Latency depends on your plan, region and how much the model decides to read; the web UI shows the analyzing state as soon as the gate passes.
Quiet turns stay visible. Acknowledgements, follow-ups and small mechanical edits produce a one-line quiet card with the gate's probabilities, so you can see why the card stayed quiet and adjust the threshold when a decision looks wrong.
Each prompt becomes a card in the web UI:
| state | shown |
|---|---|
| checking | the prompt and a progress bar (gate in flight) |
| analyzing | the gap flags and risk level from the gate, while the brain works |
| done | the perspectives the brain applied and its items, sorted by severity, each with a copy button, plus the model, time and tokens it took |
| quiet | one grey line: the reason and the probabilities |
| gate unavailable | the gate call failed (timeout, key, network); no analysis was run |
| stopped | the daemon shut down while this analysis was running |
Every finished card ends with a meta line: the agent, the gate time, the brain time, the model, the input tokens summed over all of the brain's turns (with how many were read from the prompt cache and how many were written to it), the largest single request (the context the model saw at once), the tokens it wrote, and for the Claude brain the number of turns and the cost in dollars. The session list on the left sums the brain tokens per session, so you can see what the reviews have spent on each project.
Items are written in the language of the prompt, whatever it is. The web UI's own labels follow the browser language and can be pinned in settings (English, Korean, Japanese, Chinese, Spanish, French, German, Portuguese, Russian, Italian). Sessions are listed on the left by project directory; the web UI switches to the session that last received a prompt.
The gear in the top bar opens settings: the web UI language, which brain runs, the Claude and Codex models, the effort level of each, and the jev model. Saving writes ~/.config/jev-blindspot/env and applies to the running daemon at once. The Codex model list comes from what Codex has cached for your account.
Requirements: Linux or macOS, Node 20 or newer, a TypeSafe API key, and the agent you use logged in: Claude Code 2.1.278 or newer with a subscription, or Codex CLI 0.144 or newer with a ChatGPT login. Each agent's prompts are analyzed by that agent's own headless mode, so you need only the one you type into.
npm install -g jev-blindspot

mkdir -p ~/.config/jev-blindspot
cat > ~/.config/jev-blindspot/env <<'EOT'
TYPESAFE_API_KEY=your-key
EOT
chmod 600 ~/.config/jev-blindspot/env

jev-blindspot install-hook   # registers the UserPromptSubmit hook with every agent found
jev-blindspot status
install-hook looks for ~/.claude and ~/.codex and registers with each; pass claude or codex to pick one. It backs up the file it edits and is a no-op when the hook is already present.
From source instead: git clone, npm install, npm run build, then use node bin/jev-blindspot.mjs in place of jev-blindspot.
The hook goes into hooks.UserPromptSubmit in ~/.claude/settings.json and runs from the next prompt on. install-hook also writes ~/.claude/commands/blindspot.md, so /blindspot prints the web UI's URL: the hook answers it itself and blocks the prompt, so no model turn is spent. /blindspot status adds daemon counters. Prompts show a claude tag in the web UI and their brain run is claude -p on your subscription.
jev-blindspot also works as a Claude Code mod. With Claude Code 2.1.287 or newer, the jev-blindspot-band mod draws a summary of the last prompt in the band above the prompt box, so you can see the result without leaving the terminal:
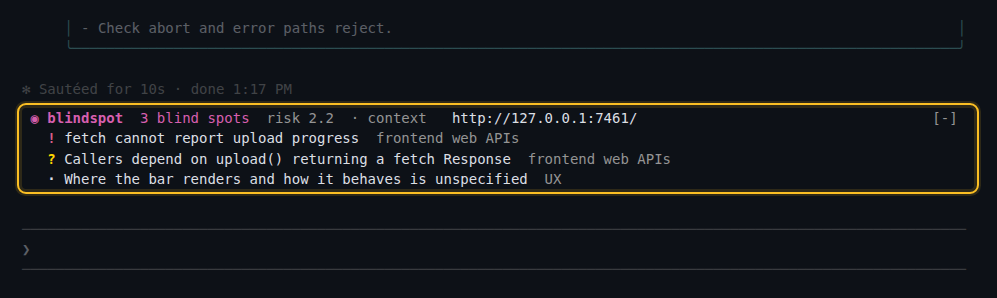
It shows "checking" as soon as you send a prompt, then the blind spot count, the deeper question when there is one, and every finding, with a link to the web UI for the full card. The mod only reads results from the local daemon: the hook above still sends the prompt, and the mod changes nothing Claude reads. Install it from this repository:
claude plugin marketplace add jsk4581/jev-blindspot
claude plugin install jev-blindspot-band@jev-blindspot --scope user
It loads from the next session. Remove it with claude plugin uninstall jev-blindspot-band@jev-blindspot --scope user.
The hook goes into ~/.codex/hooks.json, and install-hook writes ~/.codex/prompts/blindspot.md, so /prompts:blindspot does the same as /blindspot above. Codex runs a hook you added only after you have trusted its definition, so after jev-blindspot install-hook codex either open Codex and trust jev-blindspot under /hooks, or run jev-blindspot install-hook codex --trust, which writes the same [hooks.state] entry to ~/.codex/config.toml that /hooks would (backup taken first). Prompts show a codex tag in the web UI and their brain run is codex exec on your ChatGPT login.
The hook starts the daemon on the first prompt. To open the web UI, type /blindspot in Claude Code or /prompts:blindspot in Codex: the URL is printed into the session by the hook itself, without a model turn, so it is the fastest way to get there from where you already are. /blindspot status adds daemon counters. Outside a session, jev-blindspot open prints the same URL, and the web UI is at http://127.0.0.1:7461/ by default. The daemon exits after 30 idle minutes when no web UI tab is open and comes back with the next prompt.
| command | what it does | ||
|---|---|---|---|
jev-blindspot status | daemon, gate key, brain, hook and config state | ||
jev-blindspot open | print the web UI's URL | ||
jev-blindspot start / stop | manage the daemon by hand | ||
jev-blindspot gate "<prompt>" [--cwd dir] | run the gate only and print every probability | ||
jev-blindspot fixtures [file] | run a fixture file through the gate; exit code is the number of mismatches | ||
jev-blindspot smoke [prompt] | post one event and wait for the card to settle | ||
| `jev-blindspot usage [--days N\ | --all] [--json]` | what the brain spent: prompts, runs, tokens, context size, cost at API prices | |
| `jev-blindspot install-hook [claude | codex | all] [--trust]` | register the hook and the /blindspot command; --trust also records Codex hook trust |
JEV_FAKE=1 replaces the gate and the brain with stubs, for checking the plumbing before adding a key.
.jev-blindspot-off in the project root orany parent directory. Do this first in repositories you are not allowed to send text out of.
JEV_BLINDSPOT_DISABLE=1.jev-blindspot entry from hooks.UserPromptSubmit in~/.claude/settings.json and, for Codex, in ~/.codex/hooks.json (the trust entry in config.toml is then inert and can be deleted). The command files ~/.claude/commands/blindspot.md and ~/.codex/prompts/blindspot.md can go too.
Per prompt, the gate request to TypeSafe contains:
{
  "prompt": "the prompt you just submitted (cut at 6000 characters)",
  "history": [
    { "user": "an earlier prompt from the same session, cut at 500 characters",
      "assistant": "the text of the reply it got, last 1500 characters" }
  ],
  "project": {
    "dir_name": "my-app", "languages": ["typescript"], "frameworks": ["react"],
    "has_tests": true, "has_ci": true, "git_branch": "main", "is_git_repo": true
  }
}
history holds the two exchanges before the current prompt, read from the agent's transcript: the prompt text and the assistant's reply text. Tool calls, tool output, and thinking are not in it. No file contents or diffs are in it either, unless a reply quoted them. Directory and branch names are; check them before enabling this in a work repository.
When the gate passes, the brain runs claude -p (Claude Code prompts) or codex exec (Codex prompts) on your own login with the prompt, the same two exchanges, the gate's flags, and the project directory. The model reads files in that directory as it sees fit (read-only: Read, Grep and Glob for Claude; a read-only sandbox for Codex), so whatever it opens is sent along, and so are your project instructions. That traffic goes to Anthropic under your Claude account, or to OpenAI under your ChatGPT account, the same as any session of that agent.
Locally, each session's prompts and results are appended to ~/.local/share/jev-blindspot/sessions/<session>.jsonl and deleted after 30 days. ~/.local/share/jev-blindspot/usage.jsonl keeps one line per gate decision and brain run (time, agent, model, token counts, cost; no prompt text) and is not deleted, so jev-blindspot usage can add up any period. Logs in ~/.local/state/jev-blindspot/ do not contain prompt text.
The daemon listens on 127.0.0.1 only unless JEV_BIND_EXTRA adds an address. On any added address, anyone who can reach the port can open the web UI; set JEV_TOKEN to require one. The routes that accept prompts and stop the daemon take loopback connections only; the settings route accepts any allowed host, since anyone who can open the web UI already sees every prompt and the settings only choose models.
Everything lives in ~/.config/jev-blindspot/env, one KEY=VALUE per line; environment variables take precedence. The settings dialog in the web UI covers the models and effort levels. The keys you are most likely to touch by hand:
TYPESAFE_API_KEY: the gate key, required.JEV_WORTH_MIN (default 0.65): the worth_checking probability from whicha prompt is analyzed. Run jev-blindspot gate "<prompt>" on a few of your own prompts and move it until quiet and analyze match what you would want.
JEV_BIND_EXTRA and JEV_TOKEN: reach the web UI from another machine, andrequire a token when you do.
The full list, with defaults, is in docs/configuration.md.
The gate decides which prompts reach the brain; in our own use about half of them do. The gate runs on TypeSafe and does not count against your Claude or ChatGPT plan. Each brain run reads the files it needs over a few requests, and every request resends the context, so input is summed over the run.
One claude -p call on Sonnet 5.5, effort low, thinking off.
| per brain run (median / p90 / max) | clean Claude Code config | heavy config (my own) |
|---|---|---|
| fixed context (first request) | 5.1k | 14.3k |
| largest request | 7.2k / 11.9k / 14.0k | 15.9k / 17.5k / 21.7k |
| input summed over the run | 23.6k / 37.6k / 65.0k | 44.7k / 62.0k / 89.8k |
| written to the prompt cache | 2.0k | 11.7k |
| output | 1.2k / 2.2k / 2.7k | 1.2k / 2.1k / 2.8k |
| cost at API list prices | $0.026 / $0.053 / $0.072 | $0.068 / $0.081 / $0.105 |
| share of the 5-hour limit on Max 5x | about 0.05% | about 0.14% |
The heavy config loads many skills, a long CLAUDE.md and memory into every session. The brain loads them too, and since they are rewritten to the prompt cache on every run, they account for most of the difference. On Max 5x, about $0.50 of brain use at API prices moved the 5-hour meter by 1%; the weekly meter did not move over 48 runs.
One codex exec call on gpt-5.6-luna, reasoning low. Measurement in progress.
The figures above were measured in October 2026 with scripts/bench-brain.mjs: 24 prompts against this repository, run twice. Plan limits are set by the vendors and change, and the meters only report whole percents. Run the script on your own setup, and use jev-blindspot usage to see what the brain has spent over time; set JEV_PLAN_USD_PER_PERCENT to turn that into a share of your plan.
--json-schema,--effort and --permission-prompts none. It runs with your settings, hooks and CLAUDE.md the way a session does; the jev-blindspot hook recognises the brain's own run and does not fire inside it. --bare is not used because it reads only ANTHROPIC_API_KEY, which subscription logins do not have.
codex exec with --output-schema, --ephemeral and--disable hooks (Codex CLI 0.144 was used). The model list differs per account; if gpt-5.6-luna is not available to you, set JEV_BRAIN_CODEX_MODEL to a light model you have.
session go in order. Two runs go at once across all sessions by default; more wait in line and none are dropped. Raise JEV_BRAIN_CONCURRENCY if you work in several sessions at the same time.
prompt,session_id, turn_id, transcript_path; rollout user_message and agent_message lines for history). The trust-hash recipe follows Codex's source and can change with a Codex release; /hooks inside Codex is always the fallback.
npm test                              # unit tests: thresholds, transcript, parser, repo scan
node bin/jev-blindspot.mjs fixtures     # gate fixtures against the real jev
node scripts/brain-try.mjs "prompt" [--codex]   # one brain run against this repository
node scripts/gate-tune.mjs            # compare question wordings over the fixtures
Layout: bin/ (the dependency-free hook and the CLI launcher), src/cli/ (commands, Codex trust recipe), src/daemon/ (HTTP, SSE, store, pipeline), src/gate/ (jev state, questions, thresholds), src/brain/ (prompt, schema, claude -p and codex exec runners), src/context/ (repository scan, transcript tail), web/ (the web UI, no build step; labels in i18n.js).
jev-blindspot is a community project and is not affiliated with TypeSafe.
hooks/blindspot-band.mjs 216 lines1// jev-blindspot band: a summary of the last prompt's blind spots, above the prompt.
2//
3// The jev-blindspot hook already sends every prompt to the local daemon; this mod
4// only reads the result back and draws it. It never changes a prompt and adds
5// nothing to what Claude reads.
6//
7// prompt.submit: note that a prompt went out, so the band shows "checking" at
8// once and the poll below runs until that prompt's turn settles.
9// session.start: read the port and panel address, show the session's last turn,
10// and start the poll.
11// ui.render (AbovePrompt): one header line, then the deeper question and every
12// finding, each cut to one row. Other mods' band content is kept below ours.
13//
14// The host reads on(...) and $.noun.method(...) from source, so they are spelled
15// literally, and helpers that take $ are top-level functions.
16
17const POLL_MS = 1500;
18// Stop polling a prompt whose turn never settles (daemon down, brain stuck).
19const ACTIVE_LIMIT_MS = 180_000;
20// The hook stamps the turn when it runs, which may be a little before this mod
21// sees the prompt; a turn this much older than the submit still counts as it.
22const SUBMIT_SLACK_MS = 5000;
23const SETTLED = new Set(["quiet", "gate_unavailable", "done", "error", "cancelled"]);
24const GAP_LABEL = {
25 missing_context: "context",
26 missing_specification: "spec",
27 unclear_instruction: "unclear",
28 multiple_context: "several asks",
29 deeper_problem: "deeper",
30};
31const SEVERITY = {
32 "likely-costly": { mark: "!", color: "red" },
33 "worth-asking": { mark: "?", color: "yellow" },
34 note: { mark: "·", color: undefined },
35};
36
37let disabled = false;
38let base = "http://127.0.0.1:7461";
39let panelUrl = "http://127.0.0.1:7461/";
40let sessionId = null;
41// What the band shows: null (nothing), or { turn } / { pending: true }.
42let view = null;
43let submittedAt = 0;
44let polling = false;
45let unreachableSince = 0;
46
47export function register(on) {
48 on("session.start", async ($, e, next) => {
49 const result = await next(e);
50 try {
51 if ((await $.env.get("JEV_BLINDSPOT_CHILD")) === "1" || (await $.env.get("JEV_BLINDSPOT_DISABLE")) === "1") {
52 disabled = true;
53 return result;
54 }
55 await readConfig($);
56 sessionId = await $.session.id();
57 const turn = await latestTurn($);
58 if (turn) view = { turn };
59 $.ui.invalidate("ui.render");
60 $.clock.every(POLL_MS, () => poll($));
61 } catch {
62 // the band stays empty
63 }
64 return result;
65 });
66
67 on("prompt.submit", async ($, e, next) => {
68 // Only prompts a person sent: not claude -p runs, task notifications or other sessions.
69 const kind = e.origin?.kind;
70 if (!disabled && (kind === "composer" || kind === "bridge") && !isCommand(e.text)) {
71 submittedAt = await $.clock.now();
72 unreachableSince = 0;
73 view = { pending: true };
74 $.ui.invalidate("ui.render");
75 }
76 return next(e);
77 });
78
79 on("ui.render", { component: "AbovePrompt" }, async ($, e, next) => {
80 if (disabled || view === null || e.props?.hasSurvey || e.props?.view?.agentId) {
81 return next(e);
82 }
83 const { Box, Text, Link } = $.ui.resolve(e);
84 const ours = band(Box, Text, Link);
85 const theirs = await next(e);
86 return Box({ flexDirection: "column", children: theirs ? [ours, theirs] : [ours] });
87 });
88}
89
90async function poll($) {
91 if (disabled || submittedAt === 0 || polling) return;
92 const now = await $.clock.now();
93 if (now - submittedAt > ACTIVE_LIMIT_MS) {
94 submittedAt = 0;
95 if (view?.pending) view = null;
96 $.ui.invalidate("ui.render");
97 return;
98 }
99 polling = true;
100 try {
101 const turn = await latestTurn($);
102 if (turn === undefined) {
103 // daemon not answering; the hook starts it, so give it a few seconds
104 if (unreachableSince === 0) unreachableSince = now;
105 if (now - unreachableSince > 6000) view = { unreachable: true };
106 } else if (turn && turn.ts >= submittedAt - SUBMIT_SLACK_MS) {
107 unreachableSince = 0;
108 view = { turn };
109 if (SETTLED.has(turn.state)) submittedAt = 0;
110 }
111 $.ui.invalidate("ui.render");
112 } finally {
113 polling = false;
114 }
115}
116
117/** The session's newest turn, null when it has none, undefined when the daemon is down. */
118async function latestTurn($) {
119 if (!sessionId) return null;
120 try {
121 const res = await $.http.fetch(`${base}/api/sessions/${encodeURIComponent(sessionId)}?limit=1`);
122 if (!res.ok) return undefined;
123 const turns = JSON.parse(res.text);
124 return Array.isArray(turns) && turns.length ? turns[turns.length - 1] : null;
125 } catch {
126 return undefined;
127 }
128}
129
130/** Port and panel address, from the environment or ~/.config/jev-blindspot/env, as the hook reads them. */
131async function readConfig($) {
132 const file = {};
133 try {
134 const home = await $.env.get("HOME");
135 const cfgHome = (await $.env.get("XDG_CONFIG_HOME")) || `${home}/.config`;
136 const text = await $.fs.read(`${cfgHome}/jev-blindspot/env`);
137 for (const raw of text.split(/\r?\n/)) {
138 const line = raw.trim();
139 const eq = line.indexOf("=");
140 if (!line || line.startsWith("#") || eq <= 0) continue;
141 file[line.slice(0, eq).trim()] = line.slice(eq + 1).trim().replace(/^["']|["']$/g, "");
142 }
143 } catch {
144 // no config file
145 }
146 const port = Number((await $.env.get("JEV_PORT")) || file.JEV_PORT) || 7461;
147 const extra = ((await $.env.get("JEV_BIND_EXTRA")) ?? file.JEV_BIND_EXTRA ?? "").split(",").map((s) => s.trim()).filter(Boolean);
148 base = `http://127.0.0.1:${port}`;
149 panelUrl = `http://${extra[0] ?? "127.0.0.1"}:${port}/`;
150}
151
152function isCommand(text) {
153 return /^\s*\//.test(String(text ?? ""));
154}
155
156function band(Box, Text, Link) {
157 const pad = (rows) => Box({ key: "band", flexDirection: "column", paddingX: 1, children: rows });
158 const head = (mark, color, words, extra = []) =>
159 Box({
160 key: "head",
161 flexDirection: "row",
162 children: [
163 Text({ key: "mark", color, bold: true, children: `${mark} blindspot ` }),
164 Text({ key: "words", color, children: words }),
165 ...extra,
166 Text({ key: "sep", dimColor: true, children: " " }),
167 Link({ key: "link", href: panelUrl, label: panelUrl }),
168 ],
169 });
170
171 if (view.pending) return pad([head("◌", "cyan", "checking…")]);
172 if (view.unreachable) return pad([head("·", undefined, "daemon not reachable")]);
173
174 const t = view.turn;
175 const risk = t.gate ? Text({ key: "risk", dimColor: true, children: ` risk ${t.gate.risk.toFixed(1)}` }) : null;
176 const flagged = (t.gate_decision?.flagged_gaps ?? []).map((k) => GAP_LABEL[k] ?? k);
177 const chips = flagged.length ? Text({ key: "gaps", dimColor: true, children: ` · ${flagged.join(", ")}` }) : null;
178 const extras = [risk, chips].filter(Boolean);
179
180 switch (t.state) {
181 case "pending":
182 return pad([head("◌", "cyan", "checking…")]);
183 case "analyzing":
184 return pad([head("◌", "cyan", "looking for blind spots…", extras)]);
185 case "quiet":
186 return pad([head("·", undefined, t.gate_decision?.reason === "duplicate" ? "same prompt, skipped" : "nothing to check", extras)]);
187 case "gate_unavailable":
188 return pad([head("·", "yellow", `gate unavailable${t.gate_failure ? ` (${t.gate_failure})` : ""}`)]);
189 case "error":
190 return pad([head("×", "red", `${t.error?.stage ?? "analysis"} failed`)]);
191 case "cancelled":
192 return pad([head("·", undefined, "cancelled")]);
193 }
194
195 // done
196 const items = t.result?.items ?? [];
197 const deeper = t.result?.deeper?.[0];
198 if (items.length === 0 && !deeper) return pad([head("✓", "green", "no blind spots", extras)]);
199 const count = `${items.length} blind spot${items.length === 1 ? "" : "s"}`;
200 const rows = [head("◉", "magenta", count, extras)];
201 if (deeper) {
202 rows.push(
203 Text({ key: "deeper", wrap: "truncate-end", children: [Text({ key: "dl", color: "magenta", children: " ↳ deeper " }), Text({ key: "dt", children: deeper.title })] }),
204 );
205 }
206 // Every finding is shown (the brain returns at most five); a band taller than
207 // the terminal allows scrolls.
208 for (const [i, it] of items.entries()) {
209 const s = SEVERITY[it.severity] ?? SEVERITY.note;
210 rows.push(
211 Text({ key: `i${i}`, wrap: "truncate-end", children: [Text({ key: "m", color: s.color, bold: true, children: ` ${s.mark} ` }), Text({ key: "t", children: it.title }), Text({ key: "d", dimColor: true, children: ` ${it.domain}` })] }),
212 );
213 }
214 return pad(rows);
215}
216